


Learn what llms.txt is, its proposed Markdown format, a correct example, how it differs from robots.txt and sitemaps, and its practical limitations.
llms.txt is a proposed Markdown file that gives AI tools a short introduction to a website and links to useful resources. For a documentation library, it can act as a starting point for finding an installation guide, an API reference or a troubleshooting page. Its usefulness depends on the tool actually finding and using it.
For website owners, the practical decision is whether another maintained content index will help a real workflow. This guide covers the format, a working example, current implementation options and a sensible way to evaluate the result. Publishing the file does not guarantee indexing, rankings, AI citations or additional traffic.
What Is llms.txt Used For?
The llms.txt proposal describes a Markdown overview that points agents toward relevant information. The file provides context and navigation; the linked resources supply the detail. It is a publishing convention whose support varies across tools.
A starting point for finding useful content
Imagine a support library with several hundred articles. An assistant answering a setup question needs the current installation instructions, not every announcement, archive and navigation menu. A carefully selected index can make that route easier to follow when the assistant uses it.
The same editorial principle applies to a service website. Clear descriptions help distinguish a product page from a tutorial or a policy. Those descriptions should explain what a resource actually contains, so a reader or tool can choose the appropriate source without guessing from a vague title.
Start with a task you can name. In a hypothetical documentation pilot, a developer needs to install the current integration and resolve an authentication error. The useful index would distinguish the installation guide, authentication reference and relevant troubleshooting page. Listing every announcement would not improve that route. This is a source-selection exercise, not evidence that publishing a file makes an assistant recommend the product.
The llms.txt Format and a Practical Example
The proposed format starts with an H1 containing the site or project name; that is its only required section. A summary blockquote and introductory text can follow. H2 sections organize lists of links, with optional descriptions beside them. Keep this overview short enough to scan and put detailed explanations on the linked pages.
Write descriptions that help someone choose a page
The example below uses a fictional documentation site. Each description tells the reader what question the destination can answer. Replace the example URLs with resources your site actually serves; changing a URL to end in .md does not create a Markdown version of that page.
Choose specific labels such as “Authentication” or “API reference.” Labels such as “Important page” give little help when several links compete for attention. Keep product versions clear when old and new documentation coexist, and remove links that duplicate the same answer without adding useful context.
# Example Developer Docs

> Official documentation for the Example API.

Use these resources for current product behavior and integration guidance.

## Guides

- [Getting started](https://example.com/docs/getting-started.md): Install the SDK and send a first request.
- [Authentication](https://example.com/docs/authentication.md): Supported credentials and security requirements.

## Reference

- [API reference](https://example.com/docs/api-reference.md): Endpoints, parameters, and responses.

## Optional

- [Release notes](https://example.com/docs/releases.md): Historical product changes.
A technically valid outline is not necessarily a useful one. Review whether the linked pages answer distinct questions and whether their descriptions would still be accurate without the surrounding website navigation. Keep the overview focused on resource selection. Detailed instructions, exceptions and product claims belong on maintained source pages, where a reader can see the evidence and version context.
What Changed in the Current Proposal?
The August 2026 revision notes clarify file scope and discovery. An article that describes llms.txt only as a root-level file now misses part of the proposal. Existing implementations should be checked against the behavior of the tools they are intended to serve.
Subdirectory files and discoverable Markdown
A file can cover a path such as /docs/llms.txt; where files overlap, the most specific one applies under the proposal. Version 2 also describes HTML link elements or HTTP Link headers for finding a page’s Markdown alternative and the llms.txt file associated with it.
The revision accepts both appended and replaced .md extensions for Markdown pages. It also treats an Optional section as a convention for secondary links, without special processing rules. These are proposed publishing behaviors, so confirm a client’s actual support before depending on automatic discovery.
Treat file generation, Markdown delivery and discovery signals as separate implementation checks. A plugin writing a root-level index does not by itself establish how another tool discovers it or which proposal features that tool understands. Record the intended client and supported behavior instead of describing every file with the same name as an identical integration.
llms.txt vs. robots.txt vs. XML Sitemaps
These files serve different purposes and can exist together. Keeping their roles separate helps prevent configuration mistakes, such as trying to express crawl restrictions inside a content guide or assuming that a listed URL must appear in search.
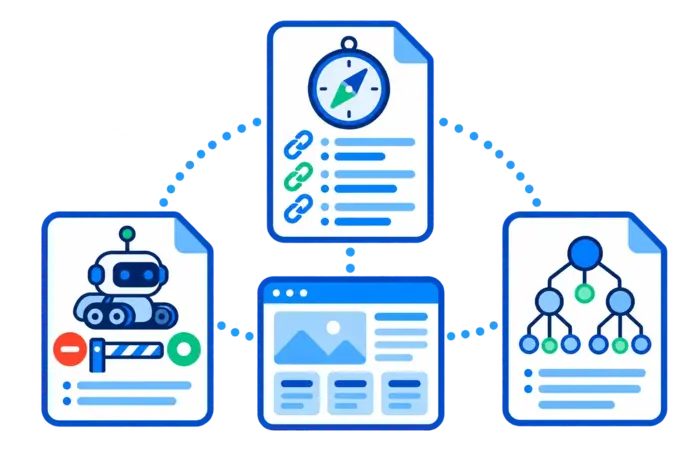
Consider a public installation guide. Its llms.txt entry can explain the setup task it answers; a sitemap can identify its URL for search discovery; robots rules communicate fetching permissions to compliant crawlers. If the guide instead returns a login screen or retired instructions, an extra index cannot repair it. Investigate the destination and intended access policy before treating another file as the solution.
| File | Main purpose | Key limitation |
|---|---|---|
llms.txt |
Introduces selected resources to tools that use the convention. | Does not ensure retrieval, citation or search visibility. |
robots.txt |
Communicates crawl rules to compliant crawlers. | Does not protect confidential pages or reliably remove indexed URLs. |
| XML sitemap | Helps search engines discover URLs and relevant metadata. | Does not guarantee crawling, indexing or rankings. |
Use the appropriate control for the job
Google’s robots.txt guidance explains that a disallowed URL can still appear in results if discovered elsewhere. If a page must be private, use authentication and appropriate access controls. A public file that lists sensitive locations is not a substitute for protecting them.
A sitemap supports discovery, especially where a site’s structure makes pages harder to find. Continue maintaining internal links, canonical URLs and accurate sitemap entries. Adding llms.txt does not remove the need for those established parts of site maintenance.
Does llms.txt Help SEO or AI Visibility?
Google states that its AI Overviews and AI Mode do not require new AI text files or special markup. Its guidance for AI features in Search emphasizes the same technical eligibility and content fundamentals used for Search. Meeting those requirements still does not guarantee inclusion.
Separate availability from demonstrated use
Several different events are often grouped under “AI visibility”: a tool requests a file, follows one of its links, uses the source in an answer, displays a citation, or sends a visitor. Evidence of the first event does not establish the later ones. A successful request alone says little about business value.
An optional content index and an actual referral are different observations. Define the AI-referred visit before treating visibility or access as traffic.
For SEOVisitor users evaluating a traffic campaign, keep acquisition and outcome reports separate from an llms.txt experiment. Record relevant visits and completed actions with your usual analytics definitions. Neither publishing this file nor buying traffic establishes that rankings or AI recommendations will improve.
Give a separate AI-source campaign its own destination, dates and reporting label. Its recorded activity answers a campaign question, while an llms.txt pilot asks whether an intended tool can find and use appropriate resources. Combining those observations can turn ordinary campaign visits into a misleading claim about earned recommendations. Keep file retrieval, cited answers and visitor outcomes as separate entries in the review.
If you need an AI-source traffic campaign for your website, you can use SEOVisitor’s AI traffic service to select an available source and the page you want to promote.
llms.txt and llms-full.txt
The filenames are easy to confuse. In implementations such as Mintlify, llms.txt is an index, while llms-full.txt brings documentation content together in one larger file. They support different ways of supplying context to a tool.
Choose an index or a content bundle deliberately
A concise index lets a tool select the pages relevant to one question. A combined file can be convenient when you explicitly want to supply a whole documentation set. Mintlify documents automatic generation of both, but other platforms may implement different outputs and update behavior.
Before offering a large bundle, consider its size, duplicated material and version consistency. Test whether the intended tool can handle it and whether individual source URLs remain clear. More text is not automatically more useful, especially when old instructions contradict current behavior.
Choose according to the task. An installation question may need a small set of current pages; a deliberate documentation review may justify supplying a broader bundle. Check what the exported content actually includes, how it identifies source pages and which versions it covers. Do not assume that two platforms’ full-content files have identical limits or visibility rules.
How to Create and Maintain an llms.txt File
Start with the information people actually need: current product documentation, setup instructions, important policies and reliable troubleshooting resources. A small, reviewed selection is easier to maintain than an export that nobody checks. Choose the publishing method after deciding who owns that selection.
For each proposed entry, record its purpose, intended audience, applicable version, owner and final destination. Leave out duplicates or retired material unless they answer a real historical-support need, in which case label that scope clearly. A public index should not become an inventory of private locations, draft offers or credentials. Review access and publication decisions at the source; descriptions in this file are not a security boundary.
Manual publishing and generated files
A manually maintained file suits a small, stable collection. Keep it alongside the website’s other managed content so changes can be reviewed and reversed. Before replacing an existing file, check whether a plugin or build process already owns it; otherwise a later update may overwrite your changes.
For WordPress, Yoast’s implementation documentation describes a root file refreshed by a weekly scheduled action and rules for choosing content. It also documents manual page selection and conflicts with existing files. Inspect the generated result rather than assuming automatic selection matches your priorities.
Keep the editable source or generator configuration separate from a copy of the served output. Record which process owns the URL and when it is expected to regenerate. If a manual correction disappears later, investigate that ownership and refresh cycle before repeatedly editing the output. A durable change belongs in the responsible source or supported configuration, followed by another check of the public result.
Keep the overview aligned with the source pages
Assign one owner to review the file when services, documentation versions or URL structures change. Descriptions should match the current destination, particularly for pricing, eligibility and policy information. If a page moves, update the link to its final location and check any Markdown alternative too.
Use a short change note for substantial revisions: which source changed, why it changed and when it was reviewed. This makes later troubleshooting easier. When a generated list omits an important guide, investigate its selection rules before adding another generator that competes for the same URL.
For the broader delivery and site-access fundamentals behind these checks, use the technical SEO guide below; an optional content index should complement a functioning website.
How to Test Whether the File Is Useful
Evaluate both technical delivery and the quality of the resulting answers. Decide what success looks like before making changes. A useful pilot might test whether an assistant consistently finds the current integration instructions for a small set of genuine support questions.
In a hypothetical pilot for a booking API, the documentation owner selects installation, authentication and troubleshooting questions. For each, identify the correct source before running the test. Record whether the file was explicitly supplied or independently discovered. Keep that condition consistent when comparing runs, and assess the returned answer against the source rather than treating confident wording as correctness.
| Task | Expected source | Evidence to record |
|---|---|---|
| Install the current integration | Current getting-started guide | Selected URL, applicable version and accurate setup answer |
| Resolve an authentication question | Authentication reference | Whether the answer follows the current documented requirements |
| Investigate a documented error | Relevant troubleshooting page | Correct source selection and any unsupported instruction |
These are test tasks, not reported results. Save the file version and the reviewed answers so a later editor can repeat the exercise. If an answer is wrong, first establish whether the issue lies in source content, description, retrieval or the tool’s interpretation; adding more links may not address the actual problem.
Check delivery, links and content
Open the published file as a visitor would and confirm that it returns readable text with a successful HTTP response. Check for an HTML error page, login screen, stale cache or redirect loop. Follow every listed link, including Markdown links, and confirm the destination contains the expected information.
Then compare a handful of descriptions with their sources. Look for expired offers, retired product versions and headings that promise more than the page explains. Repeat this check after a migration or major content update, when an apparently valid URL may point to the wrong page.
A successful response code is only the start. A Markdown URL can still return a generic HTML page or an out-of-date export. Compare the actual content with the intended resource and check the advertised discovery path where the implementation uses one. Keep a record of the final URL and the checked version rather than marking a link correct simply because it opened.
Run repeatable questions and interpret logs carefully
Choose a fixed set of questions and record the tool, date, instructions and sources it used. For a controlled usability check, give it the file as a starting point and inspect whether it selects suitable resources. That demonstrates the file’s usefulness when provided, not that every assistant discovers it independently.
Server logs can show requests, but a user-agent label by itself is weak evidence of identity or downstream use. Combine observable requests with cited answers, referral data and relevant conversions where available. Avoid attributing a traffic change to llms.txt when campaigns, content updates or seasonality changed at the same time.
Record failures as useful findings: a retired guide selected, an unavailable Markdown URL, or an answer that does not follow its cited source. Repeat the task after the specific correction while retaining the original result. A supplied-index usability check can demonstrate a clearer route to information, but it cannot establish that an unrelated assistant adopted the file or caused new visits.
Common Implementation Mistakes
Most avoidable problems come from weak source selection, unclear ownership or exaggerated expectations. Use the following checks before treating the file as finished, and repeat them when the website changes.
- Broken Markdown links: Appending .md without publishing a corresponding resource.
- Conflicting ownership: Allowing several plugins or deployment processes to generate the same file.
- Outdated descriptions: Keeping summaries that no longer match the linked page.
- Excessive scope: Including archives and duplicate pages without a clear reason.
- Confused controls: Treating prose in llms.txt as an enforceable crawler rule or training opt-out.
- Unsupported reporting: Calling a file request proof of rankings, citations or revenue.
Should Your Website Use llms.txt?
Our recommendation is to try a small implementation when there is a clear documentation or support use case, an intended tool that can use the file and someone responsible for keeping it accurate. Allocate effort according to the problem it solves, rather than the popularity of the filename.
For a small site with straightforward navigation, stronger source pages may deserve attention first. If you already have a generator, review its output and test a few realistic questions before investing in extensive customization. Keep the file only as complex as the workflow requires.
Continue the pilot when it solves a documented information-finding problem at an acceptable maintenance cost. Revise it when descriptions or links repeatedly misdirect the intended tool. Defer expansion when the source material is weak or nobody can maintain it. A realistic decision can be to keep a small reviewed index without making an SEO or AI-visibility claim.
Conclusion
An llms.txt file can provide a useful introduction to a website’s resources for participating AI tools. A good implementation starts with accurate source content, clear descriptions, working links and a maintenance owner. The current proposal also clarifies subdirectory scope and ways to advertise related Markdown resources.
Evaluate it through specific tasks and observable results. Continue maintaining your site’s crawl controls, sitemaps, internal links and access protections, and avoid promising outcomes the file cannot ensure. A modest, tested implementation is easier to justify than a broad claim about future visibility.
Frequently Asked Questions
Quick answers to common questions about llms.txt
No. Google says its AI search features do not require new AI text files or special markup. A page must meet normal Search eligibility requirements, and inclusion is not guaranteed.
No. llms.txt provides content guidance, not enforceable access restrictions or a training opt-out. Use the relevant provider’s documented crawler controls and protect private content with authentication.
llms.txt is usually a concise index of resources. In implementations such as Mintlify, llms-full.txt combines documentation content into one larger file. Check your platform’s output and the receiving tool’s limits.
Yes. The current proposal supports files such as /docs/llms.txt for the pages under that path. Where files overlap, the most specific file applies under the proposal; client support should still be checked.
No. Your website or publishing platform must actually serve a Markdown version at that address. Open each link and verify its response and content before including it in llms.txt.
No. A small file can be maintained manually through your normal publishing process. A generator may suit a changing documentation set; first identify who owns the URL and how the output is refreshed.
Choose reliable resources that answer real tasks, with clear descriptions and version scope. Avoid duplicate or retired material without a useful reason, and do not use a public index to expose private content.
A plugin, scheduled task or build process may regenerate the output. Check which process owns it and make the correction in the responsible source or supported configuration before verifying the public file again.
Record the task, tool, file version and selected sources, and distinguish explicitly supplying the index from independent discovery. A correct answer or file request alone does not prove that the assistant discovered and used the file.
No. A file request is evidence of access, not a person following an AI-generated link to your website. Keep retrieval logs, citations, recorded visits and business outcomes as separate observations.

Comments
Leave a Comment