


Learn how to separate real users from suspicious bot traffic using GA4, CDN and server logs—without filtering valid visitors or corrupting raw analytics data.
Traffic reports can look convincing even when part of the activity is automated. A sudden increase in sessions, an unusual country, a high bounce rate, or a group of very short visits may deserve investigation—but none of those signals proves that a visitor is a bot.
Accurately separating real users from bot traffic requires evidence from more than one layer. Analytics tools can reveal suspicious patterns, while CDN data, web application firewall events, and server logs provide the technical context needed to validate them. The safest principle is simple: segment first, compare the pattern, validate it, and only then exclude or block traffic.
This guide explains how to evaluate traffic quality without deleting legitimate user data, misclassifying low-intent visitors, or treating a single GA4 metric as definitive proof.
What Is Real User Traffic?
Real user traffic comes from people visiting a website to read content, compare an offer, solve a problem, complete a task, or explore a product. Human visitors can arrive through search engines, advertising, social media, referrals, email, or direct navigation.
Human behavior is variable. One visitor may read several pages and convert, while another may find the answer in a few seconds and leave. A legitimate user may also browse through a VPN, an embedded mobile browser, a privacy tool, or an accessibility application. These differences are why engagement metrics should be interpreted as context rather than proof of identity.
Real traffic is most valuable when it matches the purpose of the page. A smaller group of visitors with relevant intent can provide better business insight than a large volume of random sessions. This distinction is explored further in our guide to qualified website traffic.
What Is Bot Traffic?
Bot traffic is generated by automated software rather than a person manually browsing the site. Not all bots are harmful, and not all automated requests should be blocked.
For the underlying mechanics, see our guide to what a traffic bot is, including how automated visits work, how GA4 records them, and the risks of artificial traffic.
Helpful bots
Search engine crawlers, uptime monitors, accessibility services, link-preview generators, and authorized integrations may request pages automatically for legitimate reasons. Blocking them indiscriminately can damage indexing, monitoring, or normal platform functionality.
Unwanted or misleading bots
Scrapers, credential-stuffing tools, form-spam programs, vulnerability scanners, fake-traffic systems, and automated ad-clicking tools can consume resources or distort reporting. Some execute JavaScript and create analytics events; others appear only in CDN or server logs because they never load the analytics tag.
GA4’s known-bot filtering removes many recognized bots and spiders from reports, but it does not detect every automated visitor. Custom, newly created, or browser-based automation can still appear in analytics data.
No Single Signal Proves a Visitor Is a Bot
The most important rule in a traffic-quality investigation is to avoid making a decision from one metric. Each suspicious pattern has legitimate alternative explanations:
- Very short sessions: the visitor may have found an immediate answer, opened the wrong result, or encountered a measurement failure.
- 100% bounce or low engagement: the page may satisfy intent without another interaction, or important events may not be configured correctly.
- Unusual geography: VPNs, corporate networks, roaming users, proxy services, and data-center routing can affect location reporting.
- Repeated browser or device values: popular device configurations naturally create repetition, especially in large campaigns.
- No CTA interaction: the user may be researching, comparing options, or simply not ready to act.
- A completed form or event: sophisticated automation can click, scroll, submit forms, and trigger custom events.
A reliable conclusion requires multiple independent signals, recurrence over time, and confirmation from a technical data source.
Real Users vs. Bot Traffic: Signals and Alternative Explanations
No single signal proves that traffic is automated. Compare multiple patterns and validate them with analytics, CDN data, or server logs before filtering any visitors.
Short, Repeated Sessions
- Possible bot explanation: Automated visits may be running on a fixed schedule.
- Possible legitimate explanation: The campaign may be attracting the wrong audience, or the landing page may be broken.
- How to validate it: Compare GA4 segments with request timing in your server or CDN logs.
One Country Suddenly Dominates
- Possible bot explanation: The traffic may originate from proxies or data-center IP addresses.
- Possible legitimate explanation: Referral exposure, VPN usage, or campaign targeting can also create a sudden geographic spike.
- How to validate it: Review the source and medium, ASN information, CDN records, and server logs.
Identical Event Sequences
- Possible bot explanation: Scripted browser automation may be repeating the same actions.
- Possible legitimate explanation: A rigid funnel design or duplicated tracking events can produce similar patterns.
- How to validate it: Examine event timestamps, tag diagnostics, and session recordings.
High Pageviews Without Conversions
- Possible bot explanation: The visits may be automated or come from low-quality traffic.
- Possible legitimate explanation: The offer may be weak, the audience intent may not match, or the conversion process may contain friction.
- How to validate it: Analyze landing-page performance and compare the results with funnel and conversion data.
Many Requests Without Analytics Events
- Possible bot explanation: A non-JavaScript crawler or scraper may be requesting the pages.
- Possible legitimate explanation: Analytics tags may have failed, consent restrictions may apply, or scripts may be blocked.
- How to validate it: Compare server or CDN logs with the visits recorded in your analytics platform.
How to Investigate Suspicious Traffic Step by Step
Investigating suspicious traffic should be a controlled validation process, not an immediate exclusion. The following workflow preserves the original data, isolates the suspicious pattern, compares multiple dimensions, validates the evidence outside GA4, and documents every decision before traffic is filtered or blocked.
1. Preserve the original data
Do not begin by deleting events or activating exclusions. Keep the original reporting data available so every decision can be reviewed later. Use a comparison, report filter, or exploration to inspect the suspected activity without changing what the property collects.
GA4 reporting comparisons and collection-level data filters do different jobs. According to Google’s data-filter documentation, an active exclusion permanently prevents matching incoming data from being processed; it cannot reconstruct that data later. Do not describe an exclusion as a reversible reporting view or use an internal-traffic rule as a general-purpose bot detector.
2. Create a suspicious-traffic segment
Build the segment around the pattern you observed—for example, a source/medium combination, landing page, country, browser, event sequence, or narrow time window. Avoid using one broad condition that can capture legitimate users.
Write down the segment’s scope. A user segment can include activity beyond the suspicious visit, whereas a session or event segment answers a narrower question. Keep the dates, time zone, dimensions, and intended unit of analysis consistent when comparing the suspect group with other traffic.
3. Compare multiple dimensions
Compare the suspected segment against the rest of the traffic using:
- Source and medium
- Landing page and navigation path
- Country and region
- Browser, operating system and device category
- Engagement depth and event sequence
- Conversion quality rather than event count alone
- Time of day and recurrence across several days
4. Validate outside GA4
Analytics shows behavioral patterns, but GA4’s IP-address limitations prevent website owners from using raw GA4 IP data for IP- or ASN-level investigation. Confirm suspicious behavior through a CDN, WAF, reverse proxy, or server logs. Look for repeated IP or ASN ranges, unnatural request intervals, sequential crawling, repeated user agents, unusual response patterns, and requests that never execute JavaScript.
5. Require multiple independent signals
One anomaly should create a question, not a verdict. A stronger case may combine repeated request timing, a data-center ASN, identical navigation, unrealistic event sequences, and recurrence over several days.
Two charts derived from the same duplicated event are not independent confirmation. Look for evidence that could contradict your hypothesis, such as a tagging release that explains the repeated sequence. Active abuse affecting availability or accounts still needs a prompt response from the responsible technical team; preserving evidence does not mean waiting for days of damage.
6. Document the decision
Record the rule, affected date range, volume of traffic, evidence used, implementation date, and a future review date. This prevents temporary assumptions from becoming permanent reporting errors.
A Hypothetical Investigation: Repeated Events, Different Causes
Imagine that a campaign landing page starts recording repeated CTA events and very short visits. This is a hypothetical example, not an SEOVisitor case study. The analyst preserves the original report, identifies the affected page and release window, and compares similar visits before and after the change.
A controlled visit then reproduces two CTA events from one action. The measurement owner finds duplicate tracking on that template. That explains the event inflation, but it does not establish that every visit was human. The analyst keeps the identity question separate and asks the infrastructure team to examine the corresponding request pattern.
| Evidence | What it supports | Next action |
|---|---|---|
| A controlled visit reproduces duplicate events | A collection defect exists | Fix the implementation and verify new events |
| Repeated abusive requests target the same form endpoint | A separate endpoint-abuse investigation is justified | Review narrowly scoped protection with the technical owner |
| Short visits occur without corroborating technical evidence | Identity remains uncertain | Keep the segment under review; inspect audience and page fit |
Suppose the logs also reveal repeated submissions with invalid payloads to a form endpoint. That supports a separate abuse finding; the duplicated analytics event did not prove it. The team addresses the form pattern at the appropriate layer and checks that legitimate submissions still work.
The final incident note records a confirmed tracking defect, a separately supported abuse pattern, and any visits whose identity remains unknown. This is more useful than labeling the entire campaign “bots” and deleting it from analysis. A lower total after the fixes is not, by itself, evidence that traffic quality improved.
What GA4 Can and Cannot Tell You About Bots
GA4 is useful for identifying anomalies in acquisition, engagement, landing pages, devices, geography, and events. It can help answer questions such as:
- Did the traffic appear suddenly?
- Is it concentrated in one source or landing page?
- Does the event sequence differ from normal visitors?
- Does the same pattern recur at regular intervals?
- Is the traffic associated with meaningful business outcomes?
However, GA4 cannot independently prove that a specific visitor is human or automated. It also does not provide website owners with raw IP addresses for investigation. Treat it as the behavioral layer of the analysis, not the final authority.
Why CDN and Server Logs Matter
CDN and server logs record requests that analytics tools may never see. They can reveal automated clients that do not execute JavaScript, repeated paths requested in sequence, high-frequency activity, suspicious status-code patterns, and requests from hosting or data-center networks.
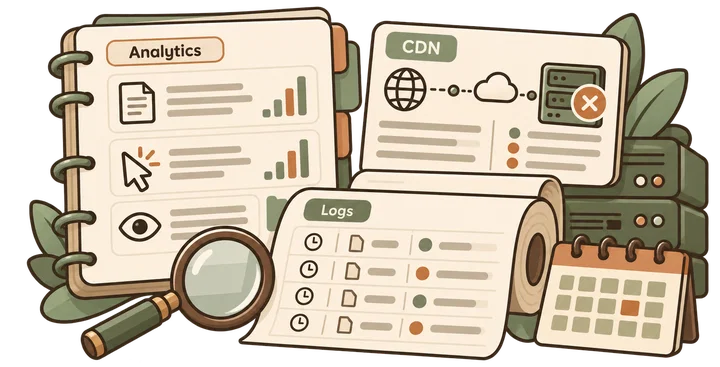
Useful technical fields include the timestamp, requested URL, response code, user agent, referrer, IP or anonymized network identifier, ASN, request method, and response size. The exact fields depend on the platform and privacy requirements.
Log evidence also needs context. A data-center ASN can belong to a legitimate monitoring service, and a repeated user agent can represent many genuine users. Validation should focus on combinations of evidence rather than a blacklist mentality.
Align the time windows and distinguish HTML requests from images, scripts, retries, and API calls. CDN records can include requests blocked at the edge that never reached the origin. One visit can generate many requests, while consent or a blocked script can prevent analytics collection. You should not expect a one-to-one match between log lines and GA4 sessions.
Sophisticated Bots Can Look Like Real Users
Modern automation can run full browsers, accept cookies, execute JavaScript, move through several pages, scroll, click buttons, and submit forms. Some systems deliberately randomize timing or device characteristics to avoid simple detection rules.
This means interaction does not automatically prove human activity. Instead of asking whether a session contains a click, investigate whether the complete behavior is plausible, varied, consistent with the traffic source, and supported by server-side evidence.
How Bot Traffic Affects SEO and Business Decisions
Bot traffic primarily damages the accuracy of analytics, capacity planning, campaign evaluation, and conversion analysis. It can make a weak campaign appear successful, hide problems in a landing page, or encourage a team to optimize for an audience that does not exist.
It is also important not to claim that GA4 metrics such as bounce rate or time on site are direct ranking factors. Google’s ranking systems documentation describes multiple systems and signals, while GA4 reporting and Google Search ranking are separate systems. The practical SEO risk is making poor decisions from distorted data—not a simple formula in which a short session directly lowers rankings.
Likewise, traffic without sales is not automatically bot traffic. The problem may be weak intent, unclear messaging, pricing, trust, usability, or checkout friction. Our guide on why a website gets traffic but no sales explains how to separate audience-quality problems from conversion problems.
Operational Lessons from Reviewing Traffic Campaigns
SEOVisitor offers website traffic campaigns, but a commercial relationship does not establish that any individual session is human or valuable. Evaluate a campaign against its documented delivery conditions and your own evidence. A service label, an engagement event, or an invoice cannot certify visitor identity.
Record the settings actually available and selected for the campaign, including its destination and delivery period. Compare those expectations with acquisition and event data, then investigate meaningful mismatches through tracking diagnostics and available infrastructure records. Do not infer that every analytics source label verifies where a visitor originated.
A separate promotion campaign can have a valid purpose once the page and measurement are ready. It does not remove unwanted bots, repair tracking, or validate the identity of existing visits. Keep its reporting distinct from your bot investigation.
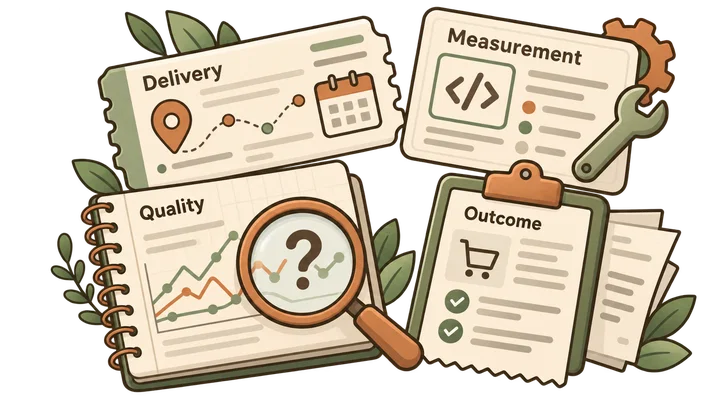
A Practical Four-Part Review
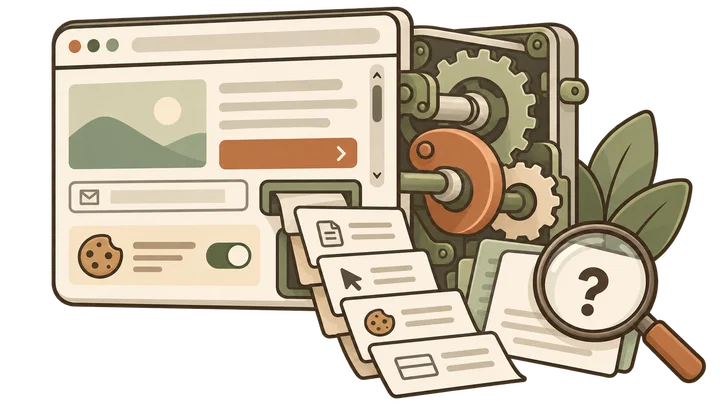
Use these four checks separately so a problem in one layer is not mistaken for a problem in another:
- Delivery: Did visits reach the correct URL, geography, device mix, and schedule?
- Measurement: Are analytics tags, consent settings, redirects, and events recording correctly?
- Traffic quality: Is the behavior varied, plausible, and consistent with the configured source?
- Business outcome: Did the traffic produce qualified actions, and if not, is the cause targeting or conversion friction?
Keeping these layers separate prevents a tracking problem, weak landing page, or targeting mismatch from being mislabeled as bot traffic—and prevents genuine automation from being dismissed as poor conversion performance.
How to Reduce Bot Traffic Without Damaging Valid Data
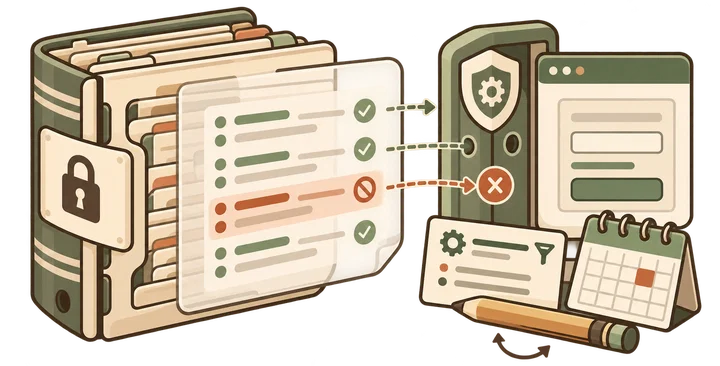
Protect the affected resource while preserving the evidence needed to review your decision. A reporting exclusion changes analysis; a security control changes access. Choose between them according to the confirmed problem, and check that useful visitors and authorized services can still complete their tasks.
Apply controls at the correct layer
Choose the control that matches both the evidence and the layer where the problem occurs:
- Use rate limiting for high-frequency abusive requests.
- Use managed bot protection or WAF challenges for verified suspicious patterns.
- Protect login, registration and form endpoints with risk-based controls.
- Use CAPTCHA selectively where abuse exists instead of adding friction everywhere.
- Fix duplicated or broken analytics events before labeling data as automated.
Prefer narrow, reviewable rules
A narrow rule based on validated behavior is safer than blocking an entire country, browser, referral source, or network. Broad rules can remove customers, employees, monitoring tools, privacy-conscious users, or search engine services.
Do not trust a Googlebot user-agent string on its own. Ask the technical owner to use Google’s crawler-verification methods before making an access decision. Where supported, inspect a proposed rule’s matches before enforcing it, then review errors, valid submissions, and known service access. Cloudflare’s guidance also recommends learning from traffic and starting with a limited scope; available controls depend on the plan.
Keep raw and cleaned reporting separate
Maintain the collected original data and create a documented reporting comparison for business analysis. If a reporting rule proves inaccurate, you can revise that comparison while the underlying data remains available. This does not recover events discarded by an active collection-level filter. Record the filter type and activation date so readers understand which historical comparisons remain valid.
A Practical Decision Framework
- Observe: identify an unusual pattern without assigning a cause.
- Segment: isolate the pattern while preserving the original data.
- Compare: evaluate acquisition, landing pages, events, devices and timing.
- Validate: confirm the pattern with CDN, WAF or server logs.
- Act: exclude from cleaned reports or block only when the evidence justifies it.
- Review: reassess the rule after a defined period.
This workflow reduces false positives and produces a more reliable traffic-quality audit.
Conclusion
The difference between real users and bot traffic cannot be determined from bounce rate, session duration, geography, or one event alone. Reliable detection combines analytics patterns with technical evidence and requires several independent signals.
The safest approach is to preserve raw data, segment suspicious activity, validate it through CDN or server logs, and document every exclusion or blocking rule. This protects reporting accuracy without removing legitimate visitors based on a misleading metric.
If you are evaluating a traffic campaign, judge it by audience relevance, measurable behavior, conversion quality, and business outcomes—not traffic volume alone. Document the traffic sources, validation rules, exclusions, and review dates so the results remain transparent and reproducible.
Frequently Asked Questions
Quick answers to common questions about real users vs bot traffic
Look for combinations of unusual signals such as repeated sessions, identical event sequences, implausible geography, abnormal device patterns, high pageviews without outcomes, and sudden source spikes. GA4 alone cannot prove every visitor is a bot.
Helpful bots support functions such as search crawling, monitoring, previews, and accessibility. Harmful or unwanted bots may scrape content, test vulnerabilities, create fake engagement, consume resources, or manipulate forms and advertising data.
Bot activity can waste server resources, distort analytics, scrape content, and lead teams to make poor SEO decisions. However, an analytics spike does not automatically change rankings, and legitimate search crawlers must not be blocked accidentally.
Yes. Advanced automation can execute JavaScript, rotate devices and locations, pause between actions, and imitate human event patterns. Reliable investigation requires multiple signals from analytics, CDN data, server logs, form quality, and business outcomes.
Server and CDN logs show requests that may never appear in analytics, including IP patterns, user agents, request frequency, status codes, paths, and timing. Comparing logs with GA4 helps reveal automated activity and measurement gaps.
Preserve raw data, create suspicious-traffic segments, validate findings with server or CDN logs, protect forms, use appropriate rate limits and bot controls, document filters, and report qualified conversions separately from total sessions.
Bot traffic is website activity generated by automated software rather than ordinary human browsing. Some bots are useful, such as legitimate search crawlers, while others scrape content, scan sites, imitate engagement, or distort analytics.
GA4 automatically excludes known bots and spiders, but this is not a guarantee that every automated visit is detected. Google does not let you disable known-bot exclusion or view its excluded volume. Validate suspicious remaining activity with additional evidence.
An active exclusion prevents matching incoming events from being processed, and that discarded data is unavailable later in Analytics or BigQuery. A report filter or exploration is different: its presentation can be revised while the underlying collected data remains available.
No. One visit can request many assets or retry requests, and CDN logs may include blocked activity that never reaches the origin. Consent, script blocking and collection differences also affect analytics. Compare relevant patterns and time windows rather than forcing the totals to match.
Geography and network ownership alone are insufficient evidence. Broad blocking can affect customers, privacy tools, monitoring services or legitimate crawlers. Combine the pattern with technical evidence and review a narrowly scoped control with the responsible owner.

Comments
Leave a Comment